什么是 ACL
DPDK 中的 ACL(Access Control List)模块提供了数据包分类功能,根据文档 Packet Classification and Access Control 中所述:
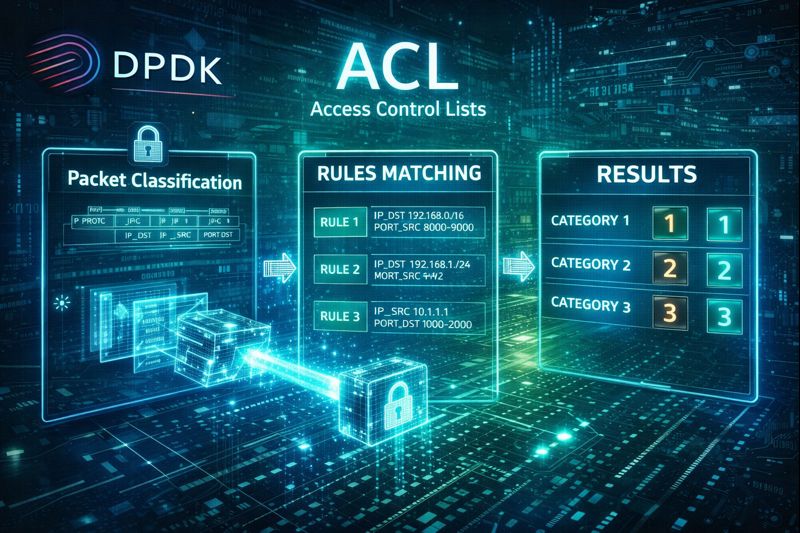
The ACL library is used to perform an N-tuple search over a set of rules with multiple categories and find the best match (highest priority) for each category.大体来说,就是事先定义一些基于数据包 N 元组的规则,每一个规则都有一个优先级,并且归属到一个或多个不同类别; 然后对于输入的数据包进行规则检查,如果该数据包满足一个类别里的某些规则,返回结果是其中优先级最高的那个,如果类别中的规则都不满足就返回 0. 显然,设定了多少个类别就会有多少个匹配结果。
举例来说,编写基于 ipv4 的 5 元组 {proto, ip_src, ip_dst, port_src, port_dst} 的规则:
Example 1:
rule 1: 返回值:1 类别:0,1 优先级:1 ip_dst:192.168.0.0/16 port_src:8000-9000
rule 2: 返回值:2 类别:0 优先级:2 ip_dst:192.168.1.0/24
rule 3: 返回值:3 类别:1 优先级:3 ip_src:10.1.1.1/32 port_dst:1000-2000
假如一个数据包的 ip_src 为 10.1.1.1, ip_dst 为 192.168.1.15, port_src 为 8080, port_dst 为 1500, 在类别 0 中, 同时满足 rule1 和 rule2, 由于 rule2 的优先级更高,因此返回 2; 在类别 1 中, 满足 rule3, 因此返回 3.
通过上述例子可以看出,使用 ACL 的关键在于:
- 规则定义:不同字段有不同的规则类型(例如 ip 地址和端口号),需要对各字段的规则进行分别定义
- 规则编写:编写具体规则内容, 制定每一条规则的返回值、类别和优先级
- 执行匹配:根据输入数据获取匹配结果
规则定义
ACL 的规则是基于 N 元组的,对 N 元组内的每一个字段来设置具体的规则内容. 其字段定义如下:
struct rte_acl_field_def {
	uint8_t  type;        /**< type - RTE_ACL_FIELD_TYPE_*. */
	uint8_t	 size;        /**< size of field 1,2,4, or 8. */
	uint8_t	 field_index; /**< index of field inside the rule. */
	uint8_t  input_index; /**< 0-N input index. */
	uint32_t offset;      /**< offset to start of field. */
};
各字段的意义:
- type: 该字段的规则类型,共有 3 种取值:
- RTE_ACL_FIELD_TYPE_MASK: 字段值 + 掩码,典型的例子是带掩码的 IP 地址
- RTE_ACL_FIELD_TYPE_RANGE: 字段值在一个范围内,典型例子是段口号范围
- RTE_ACL_FIELD_TYPE_BITMASK: 字段值由掩码指定的的几个比特位表示,典型例子是协议号
- size: 该字段的大小,可以是 1,2,4,8 个字节,不可以随意设置,原因见后面
- field_index: 该字段是第几个字段
- input_index: 该字段属于那个分组,具体见后面
- offset: 该字段的偏移量
需要注意的是,基于优化考虑,DPDK 在内部实现时对输入的 N 元组数据进行 4 字节分组 (group),具体来说,第 0 个字段要求必须是 1 字节(size 为 1),属于第 0 组(input_field 为 0),后面每 4 字节算作一组,所以除了第 0 个字段以外,其余字段的 size 必须要能凑成 4 字节的分组。例如,字段大小分别设置为(1, 2, 1, 2, 2) 就是错误的,因为 2 +1=3, 2+1+2=5, 字段 3 跨越了 group1 和 group2。
了解了 ACL 字段之后,我们就可以对具体的 N 元组定义规则了。以 IPv4 的 5 元组为例:
struct ipv4_5tuple {
   uint8_t proto;
   uint32_t ip_src;
   uint32_t ip_dst;
   uint16_t port_src;
   uint16_t port_dst;
};
struct rte_acl_field_def ipv4_defs[5] = {
   /* first input field - always one byte long. */
   {
       .type = RTE_ACL_FIELD_TYPE_BITMASK,
       .size = sizeof (uint8_t),
       .field_index = 0,
       .input_index = 0,
       .offset = offsetof (struct ipv4_5tuple, proto),
   },
   /* next input field (IPv4 source address) - 4 consecutive bytes. */
   {
       .type = RTE_ACL_FIELD_TYPE_MASK,
       .size = sizeof (uint32_t),
       .field_index = 1,
       .input_index = 1,
      .offset = offsetof (struct ipv4_5tuple, ip_src),
   },
   /* next input field (IPv4 destination address) - 4 consecutive bytes. */
   {
       .type = RTE_ACL_FIELD_TYPE_MASK,
       .size = sizeof (uint32_t),
       .field_index = 2,
       .input_index = 2,
      .offset = offsetof (struct ipv4_5tuple, ip_dst),
   },
   /*
    * Next 2 fields (src & dst ports) form 4 consecutive bytes.
    * They share the same input index.
    */
   {
       .type = RTE_ACL_FIELD_TYPE_RANGE,
       .size = sizeof (uint16_t),
       .field_index = 3,
       .input_index = 3,
       .offset = offsetof (struct ipv4_5tuple, port_src),
   },
   {
       .type = RTE_ACL_FIELD_TYPE_RANGE,
       .size = sizeof (uint16_t),
       .field_index = 4,
       .input_index = 3,
       .offset = offsetof (struct ipv4_5tuple, port_dst),
   },
};
最后,使用宏 RTE_ACL_RULE_DEF 定义 rule 结构体:
RTE_ACL_RULE_DEF(acl_ipv4_rule, RTE_DIM(ipv4_defs));
该宏的定义如下:
#define RTE_ACL_RULE_DEF(name, fld_num) struct name {\
struct rte_acl_rule_data data; \
struct rte_acl_field field[fld_num]; \
}这样,我们的 ipv4 规则就被定义为struct acl_ipv4_rule。
规则编写
有了规则定义,就可以按照需求编写具体的规则。在实际应用中,分类规则一般是由配置文件等方式按需配置,这里用最简单的硬编码来编写 Example 1 中的规则:
struct acl_ipv4_rule acl_rules[] = {
    {.data = {.userdata = 1, .category_mask = 3, .priority = 1},
        .field[2] = {.value.u32 = IPv4(192,168,0,0),. mask_range.u32 = 16,},
        .field[3] = {.value.u16 = 8000, .mask_range.u16 = 9000,},
        .field[4] = {.value.u16 = 0, .mask_range.u16 = 0xffff,},
    },
    {.data = {.userdata = 2, .category_mask = 1, .priority = 2},
        .field[2] = {.value.u32 = IPv4(192,168,1,0),. mask_range.u32 = 24,},
        .field[3] = {.value.u16 = 0, .mask_range.u16 = 0xffff,},
        .field[4] = {.value.u16 = 0, .mask_range.u16 = 0xffff,},
    },
    {.data = {.userdata = 3, .category_mask = 2, .priority = 3},
        .field[1] = {.value.u32 = IPv4(10,1,1,1),. mask_range.u32 = 32,},
        .field[3] = {.value.u16 = 0, .mask_range.u16 = 0xffff,},
        .field[4] = {.value.u16 = 1000, .mask_range.u16 = 2000,},
    },

};
下面解释一下编写方法。这里的 struct acl_ipv4_rule 就是刚刚通过 RTE_ACL_RULE_DEF 定义的规则类型,其中包含两个结构体字段 data 和field。
data字段的结构体定义为:
struct rte_acl_rule_data {
	uint32_t category_mask; /**< Mask of categories for that rule. */
	int32_t  priority;      /**< Priority for that rule. */
	uint32_t userdata;      /**< Associated with the rule user data. */
};
其中 category_mask 是类别掩码,32 位中每一位代表一个类别,该规则属于哪个类别就将哪一位置 1;priority是优先级,值越大表明优先级越高;userdata是用户自定义的一个数值(不能是 0),当某个规则匹配成功时,就会返回该规则的userdata。
field字段的结构体定义为:
struct rte_acl_field {
	union rte_acl_field_types value;
	/**< a 1,2,4, or 8 byte value of the field. */
	union rte_acl_field_types mask_range;
	/**<
	 * depending on field type:
	 * mask -> 1.2.3.4/32 value=0x1020304, mask_range=32,
	 * range -> 0 : 65535 value=0, mask_range=65535,
	 * bitmask -> 0x06/0xff value=6, mask_range=0xff.
	 */
};
其中联合体 union rte_acl_field_types 定义为:
union rte_acl_field_types {
	uint8_t  u8;
	uint16_t u16;
	uint32_t u32;
	uint64_t u64;
};
对应了 1,2,4,8 四种字段长度。field字段要根据先前定义的字段类型设置其值,具体来说:
- 如果字段类型为 mask,则 value 是基值,mask_range 是掩码长度。1.2.3.4/32 表示为
value=0x1020304, mask_range=32 - 如果字段类型为 range, 则 value 是范围下界,mask_range 是范围上界。0-65535 表示为
value=0, mask_range=65535 - 如果字段类型为 bitmask, 则 value 是预期值,mask_range 是掩码。0x06/0xff 表示为
value=6, mask_range=0xff
执行匹配
要执行匹配,首先需要创建规则上下文,相关代码如下:
struct rte_acl_ctx * acx;
int ret;
struct rte_acl_param prm = {
    .name = "ACL_example",
    .socket_id = SOCKET_ID_ANY,
    .rule_size = RTE_ACL_RULE_SZ(RTE_DIM(ipv4_defs)),
    .max_rule_num = 8,
};
if ((acx = rte_acl_create(&prm)) == NULL) {/* handle context create failure. */}
接下来需要在刚刚创建的空上下文中添加规则:
ret = rte_acl_add_rules(acx, acl_rules, RTE_DIM(acl_rules));
if (ret != 0) {/* handle error at adding ACL rules. */}
这样,就把 Example 1 中的规则加入到上下文中。
然后需要构建运行时结构:
struct rte_acl_config cfg;
cfg.num_categories = 2;
cfg.num_fields = RTE_DIM(ipv4_defs);
cfg.max_size = 0x800000;
memcpy(cfg.defs, ipv4_defs, sizeof (ipv4_defs));
ret = rte_acl_build(acx, &cfg);
if (ret != 0 && ret != -ERANGE) {/* handle error at build runtime structures for ACL context. */} else if (ret == -ERANGE) {
   cfg.max_size = 0;
   ret = rte_acl_build(acx, &cfg);
}
这里的 cfg 是构建运行时结构的配置,其定义如下:
struct rte_acl_config {
	uint32_t num_categories; /**< Number of categories to build with. */
	uint32_t num_fields;     /**< Number of field definitions. */
	struct rte_acl_field_def defs[RTE_ACL_MAX_FIELDS];
	/**< array of field definitions. */
	size_t max_size;
	/**< max memory limit for internal run-time structures. */
};
其他字段都很好理解,主要注意其中的 max_size 字段,该字段用来规定 ACL 运行时的内存上限,但是如果内存过小会增加分类时间,因此这是一个折中的设置选项。如果设置为 0 则会尽量减少内存占用,但不会保证使用限度。
至此执行规则的上下文创建完毕。对于一组输入数据,只要通过函数 rte_acl_classify 即可执行匹配,该函数原型如下:
int rte_acl_classify(const struct rte_acl_ctx *ctx,
		 const uint8_t **data,
		 uint32_t *results, uint32_t num,
		 uint32_t categories);
其中 ctx 即构建好的上下文了;data可以理解为一个指针数组:const uint8_t *data[INPUT_COUNT],其每一个元素指针指向一条 待匹配二进制数据。注意要进行匹配的二进制数据必须是按照网络字节序存储的;num表示 data 中的数据数量;categories是类别的数量;results是用来保存结果的数组,由于 data 中每一条数据都有 categories 个匹配结果,因此 results 的大小至少为categories * num。